Where is NS-518206? It's been a week.
check_order
It shipped Monday with UPS and arrives Thursday.
Fine.
Passed
Simulate real customers and catch multi-turn failures, hallucinations, and bad tool calls before your customers do.
“Voxli becomes more valuable the longer you’ve used it. The tests you build become a custom dataset your competitors don’t have.”

Expertise.ai runs Voxli nightly to catch agent regressions before customers do. Built with our design partners. Read the story
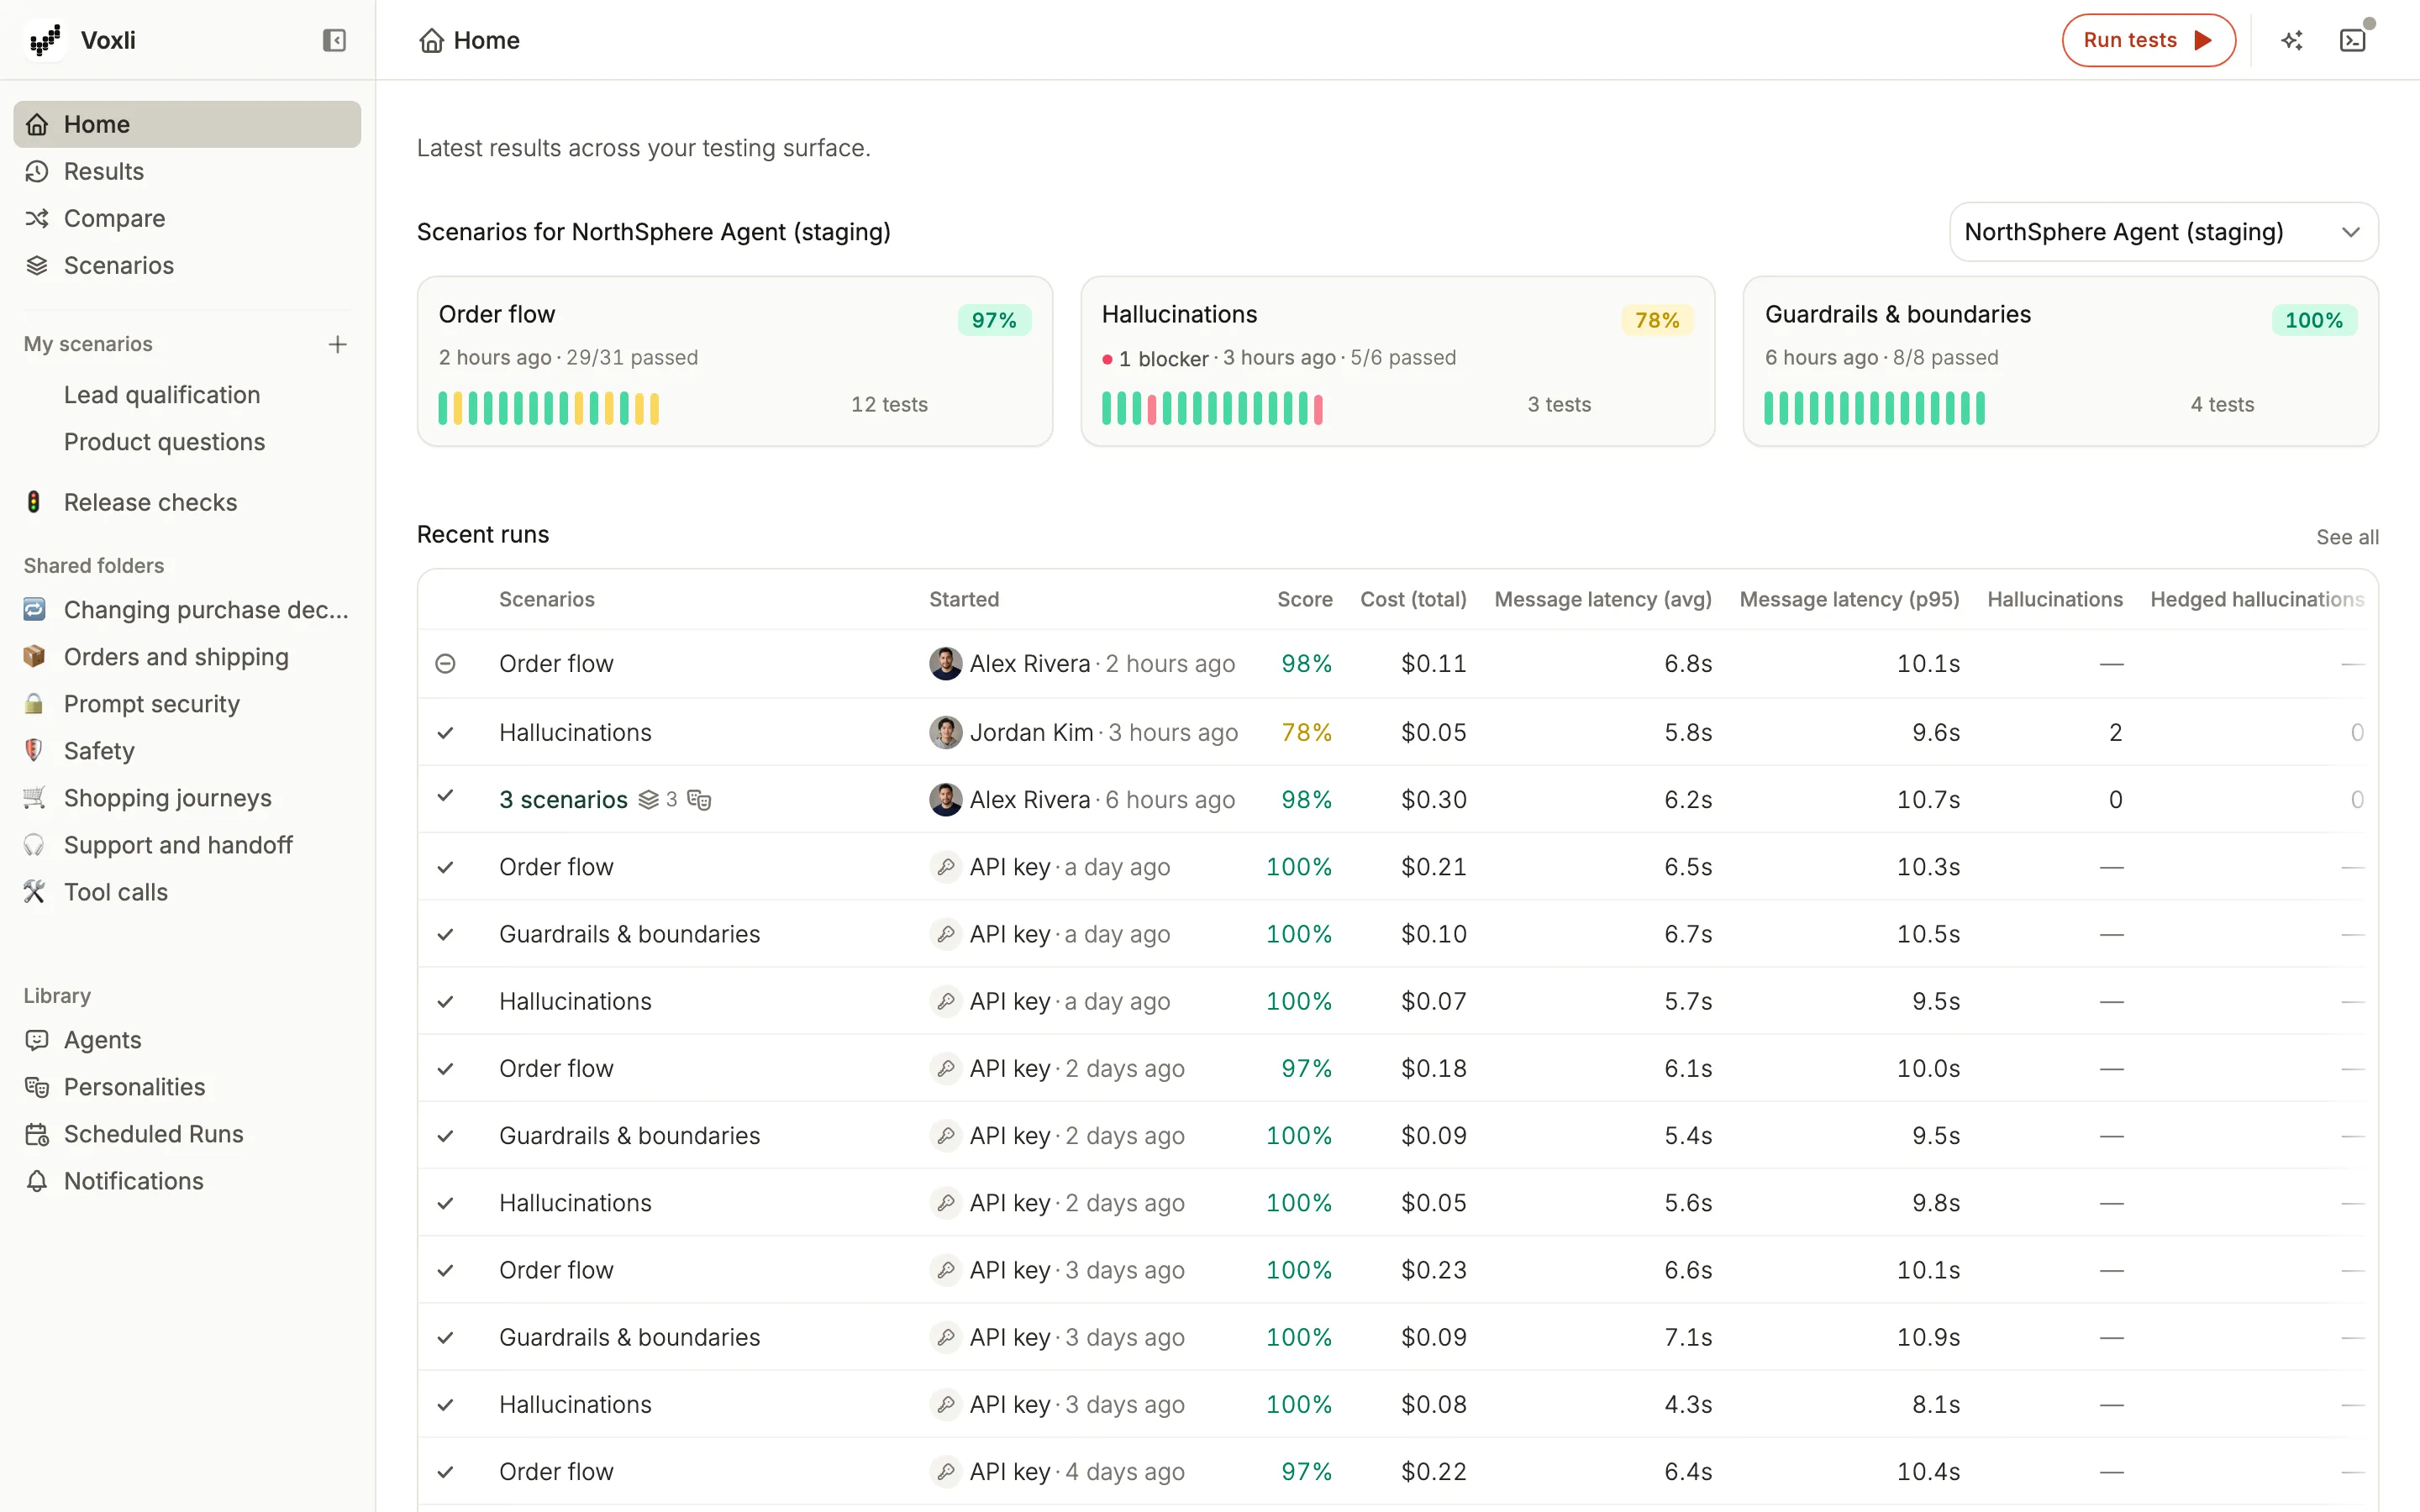
Run hundreds of tests in parallel. Create impatient, confused, and combative personas to uncover failures a happy-path demo never reveals.
Every run flags hallucinated answers, broken tool calls, and wrong parameters, and ties the evidence to the exact turn.
Run the same scenario with different user personas to catch edge cases automatically.
It talks to your agent first, then runs every test it writes.
Fix the agent and it passes.
Turn a real conversation into a repeatable test.
“The ability to replay real production conversations and turn them into repeatable tests solves a big and important problem for us.”
Use cases
Start from the change you are about to make.
Run the old model and the new one on the same suite and see exactly what changed.
Know when a change makes your agent invent facts, before a customer acts on one.
Turn the use cases, brand rules, and safety limits you agreed on into a pre-launch suite.
Run the whole suite on every change, on a schedule or in CI, and get alerted when a flow breaks.
Check that the agent calls the right tool with the right arguments and reports what it actually did.
Import the conversation that went wrong, replay it until the failure shows itself, and keep it as a test.
For developers
Connect Claude Code, Cursor, or any MCP client to your Voxli workspace. Your assistant reads the failing run, applies a fix, and runs the tests again.
More on MCPConnect your workspace
claude mcp add voxli --transport http https://api.voxli.io/mcpThen ask your assistant
Look up the latest run in Voxli and analyze why it failed.
“We had our development team spend three months building internal tools to handle what Voxli does out-of-the-box.”
Compare agent versions side by side after a model swap, prompt change, or tool update. Every test scores against your baseline.
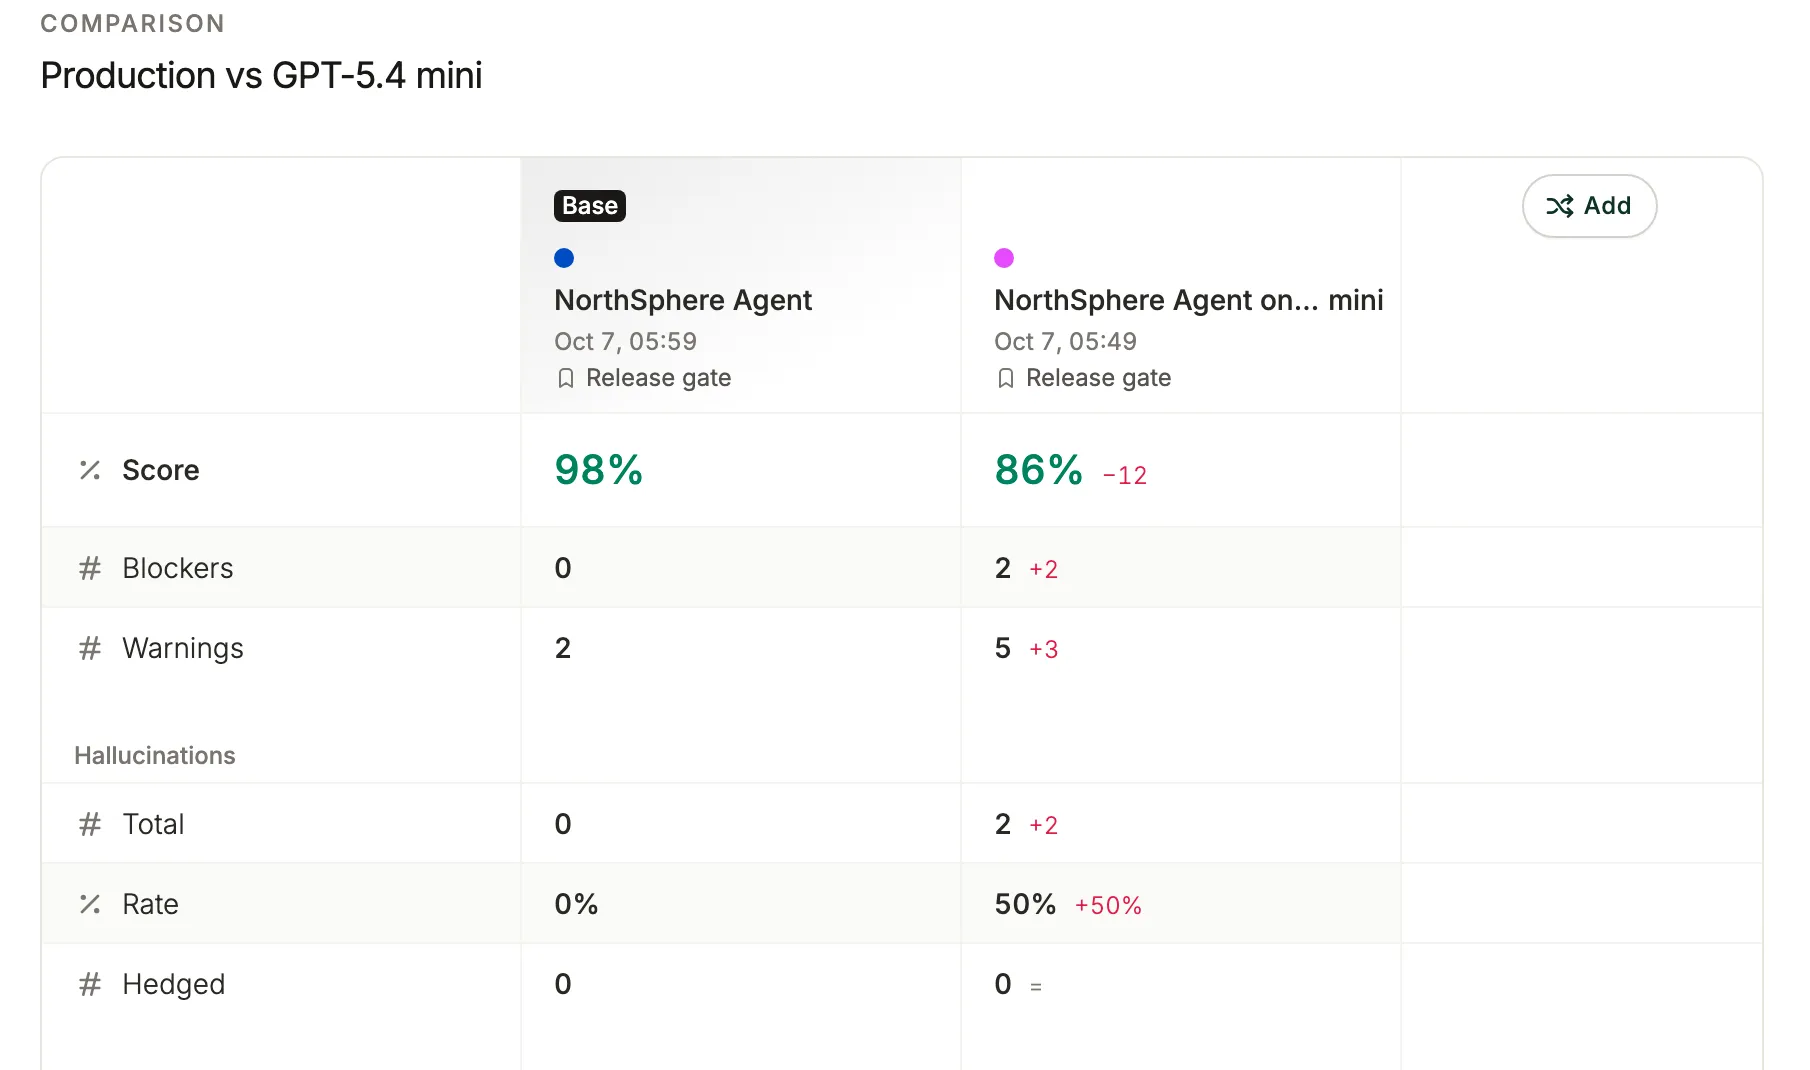
Run two or more agents on the same suite and see exactly which tests moved.
Run each test several times and read aggregated scores instead of a single lucky pass.
A short product walkthrough recorded by one of the founders.
We are early stage and founder led. Book a call and talk directly with the people building Voxli.
Talk to a founder